The best AI in this product is the AI you never see. Designed from a real research base. Four narrow agents that prevent failures instead of apologising for them.
Riders weren't leaving over price or roads. They were leaving because the system surprised them — locks that lie, batteries that die mid-route, charges with no evidence.
Killed the obvious chatbot. Designed four narrow agents that resolve failures before the rider meets them, and stay silent otherwise.
A chatbot is a well-designed apology for a failure that should have been prevented.
Real: the 2026 research base — system study, field observation, 23 rider interviews, personas, journey maps, SWOT and gap analysis — by a team of three (Aalvee Damle, Bhanuja Dass, Vrinda Singh) for a service design course.
A design exploration: everything after it is mine and was never shipped to a live fleet. Evaluation results come from scripted scenarios — directional, not empirical.
Riders had made peace with price and roads. They hadn't made peace with a system that behaved unpredictably.
The journey map's after-ride complaints look like six equal problems. Three — roads, infrastructure, storage — are outside the product's control. The other three are reliability failures the product causes.
The personas describe riders as "price-conscious but not a constraint". Unpredictability was the one thing nobody had accepted.
I gave the model the whole corpus at once, and briefed it to make agreement expensive.
"App could be smooth", "weak tracking", "poor locking" and "payment doesn't go through" are one failure in four costumes: the rider can't tell what state the system is in.
The model caught that the team's own fix adds a cash step the research calls friction. But it blamed ground staff, who actually rescue failed rides. I reframed it as charges the rider can't evidence.
A plausible fifth cluster built from one journey-map cell, with no interview behind it. Proof that model output is a proposal, not a finding.
All 23 participants were beginners, so the data can't support retention claims. Every retention claim below is framed as a hypothesis with a test.
Four directions, scored against criteria written before I saw them. The chatbot had the highest demo value and the lowest product value.
Show real bike state before she commits: verified lock, live battery, confirmed availability.
Necessary, not sufficientNo ₹250 deposit, no cash, auto-settle from a wallet. The research team's recommendation, fully digital.
Table stakes in 2026A conversational assistant for unlock failures, disputes and route questions.
RejectedNo chat surface and no score shown to the rider. Single-purpose agents decide what appears on the map, whether this bike can make this trip, and how a dispute resolves — surfacing only when a human should make the call.
Chosen — designed and prototyped below| Direction | Evidence support |
Needs AI to work |
Cost of being wrong |
User control |
Buildable as a proto |
Result |
|---|---|---|---|---|---|---|
| H1 Trust layer | 5 | 1 | 4 | 4 | 5 | Folded into H4 |
| H2 Wallet billing | 5 | 1 | 3 | 4 | 5 | Folded into H4 |
| H3 AI concierge | 2 | 5 | 2 | 3 | 4 | Rejected |
| H5 Crowd-sourced health Model-generated | 3 | 2 | 2 | 3 | 5 | Rejected |
| H4 Invisible agents | 5 | 4 | 5 | 4 | 3 | Chosen |
I designed for the daily rider — and named the rider that choice leaves behind.
AI did the volume, pattern-finding and first drafts. Every decision about what the product is stayed with me.
Most of this system is thresholds and a decay curve — because most of it should be.
| Capability | Implementation | Why it stays dumb |
|---|---|---|
| Pricing | Fixed rate table | A rider must be able to predict her fare before she commits. |
| Zone geofencing | Polygon containment | A bike is in a zone or it isn't. A probabilistic answer to "can I end my ride" would be cruel. |
| Payment state | Explicit state machine | Money movement should be auditable step by step, not interrogated. |
| Fare stop on failure | Event-triggered rule | Battery death or an unconfirmed lock stops the meter instantly. Refunds are judgement; stopping the charge isn't. |
A capability earns a model when its input is incomplete, its output open-ended, and a wrong answer recoverable. Billing meets all three. Pricing, geofencing and payments meet none.
Silence is the default. The AI speaks only when a human needs to make the call.
Precise, but it hands the decision back: she has to turn "71%" into "will this get me to work" in traffic.
Rejected — offloads the judgementFast to read, but amber is an invitation. The late rider takes it and walks toward a predicted failure.
Rejected — invites the gambleA bike that can't make this trip isn't on the map. The mental model is one sentence: if it's here, it can get me there.
ChosenA bike only shows if its predicted range covers 1.5× the trip (never under 2 km) and its lock, GPS and service checks pass.
Readiness recomputes whenever the destination changes, so search became the entry point of the whole ride.
An empty map names the check — "none have the range for 6.2 km" — and the sheet narrates removals, so a vanishing pin reads as a decision, not a glitch.
It reappears only as the thin-margin tag and notice. Three of seventeen screens show an agent speaking; the other fourteen are agents working.
The spec is the design document. The prompt is its implementation — and it took three versions to match.
| Agent | May do | May never do |
|---|---|---|
| Bike Readiness | Hide a bike. Flag it for pickup. Block ride start until the lock opens. | Show a bike it isn't confident about. Hide one without a reason. |
| Battery Decay | Hide bikes below requirement. Raise a marginal-trip notice. | Block the ride — "Continue" is always available. |
| Billing Resolution the LLM | Lower a fare. Escalate to a human. Write one sentence to the rider. | Raise a fare. Cite anything not in the ride data. Offer anything not on its action list. |
| Dispatch | Rank staff tasks, each with a reason. | Act without a human, or ignore a staff override. |
Hiding a working bike costs 40 seconds. Showing a broken one costs the relationship.
If the system can't prove the rider owes it, she doesn't.
Every automated decision explains itself the moment it becomes visible.
Fluent and unusable. Invented discounts and callbacks the product doesn't have, asserted faults the data didn't show, and often decided nothing.
Invented remedies disappeared. But under ambiguity it quietly sided with the company, and wrote timestamps at riders.
Ambiguity escalates, fares only go down, and messages are two plain sentences in clock time — no apology.
On one clean ride, V3 escalated instead of closing the case. I accepted it: over-escalating costs a reviewer a few minutes; under-escalating charges riders for failures nobody could prove.
An agent that cannot see who you are cannot treat you differently for being you. Enforced at the context layer, where a later prompt tweak can't quietly undo it.
Grayscale first, so nothing was decided by colour — and failure states designed alongside the happy path, not after it.
| Component | Spec | The decision inside it |
|---|---|---|
| Notices, two weights | Failure screen · inline note | Failure screens lead with an icon and a bold heading; inline notes (thin margin, under review) are a tinted box whose words carry the whole meaning. Meaning never rides on colour alone. |
| The list is not secondary | Bottom sheet mirrors every map pin | Screen-reader users get the full core task, not a reduced version of it. |
| Manual bike-ID entry | First-class, not a fallback | Scanning a QR code needs visual targeting and steady motor control that not every rider has. |
| Throttled live updates | Announced once a minute | Fare and range change constantly; announcing every tick floods a screen reader. |
Five stop a bad ride before it starts. Five handle the failures the hardware still causes, so the cost lands on the system instead of on Ananya.
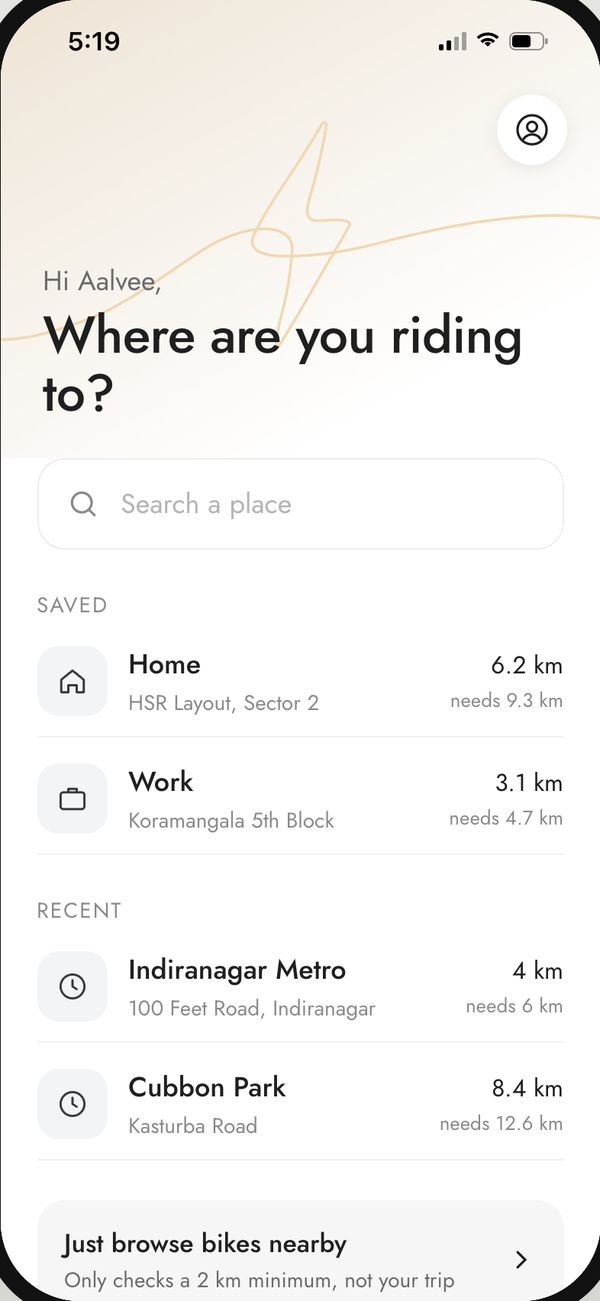
PainA bike that died 2 km from her office.
She says where she’s going before she sees a bike, and every saved trip shows the range it needs.
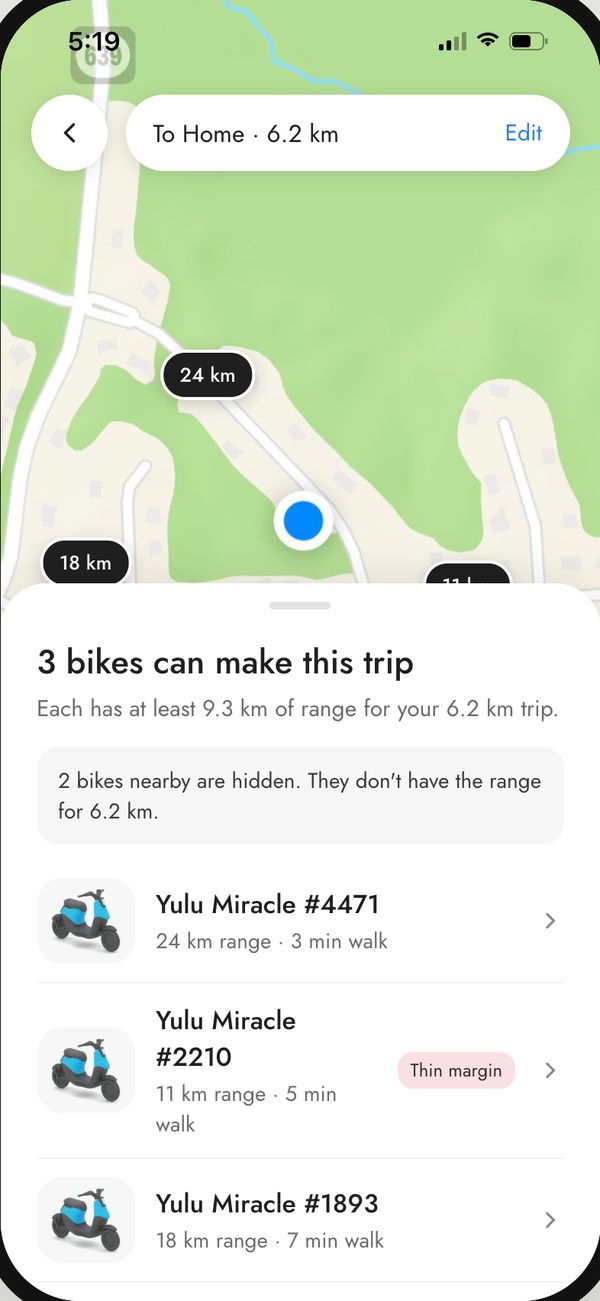
PainThe map offered bikes that couldn’t make the trip.
Only bikes that clear the trip appear. The two that don’t get one line, never a score.
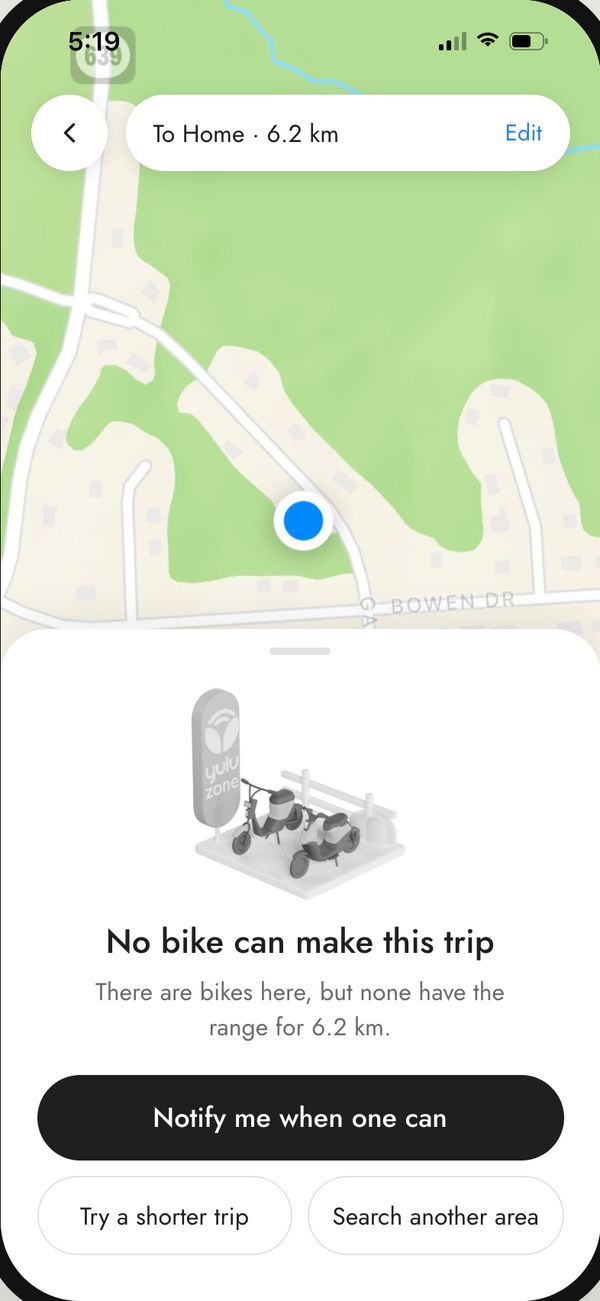
PainAn empty map reads as a broken app.
The screen names the check it ran and gives her three ways forward.
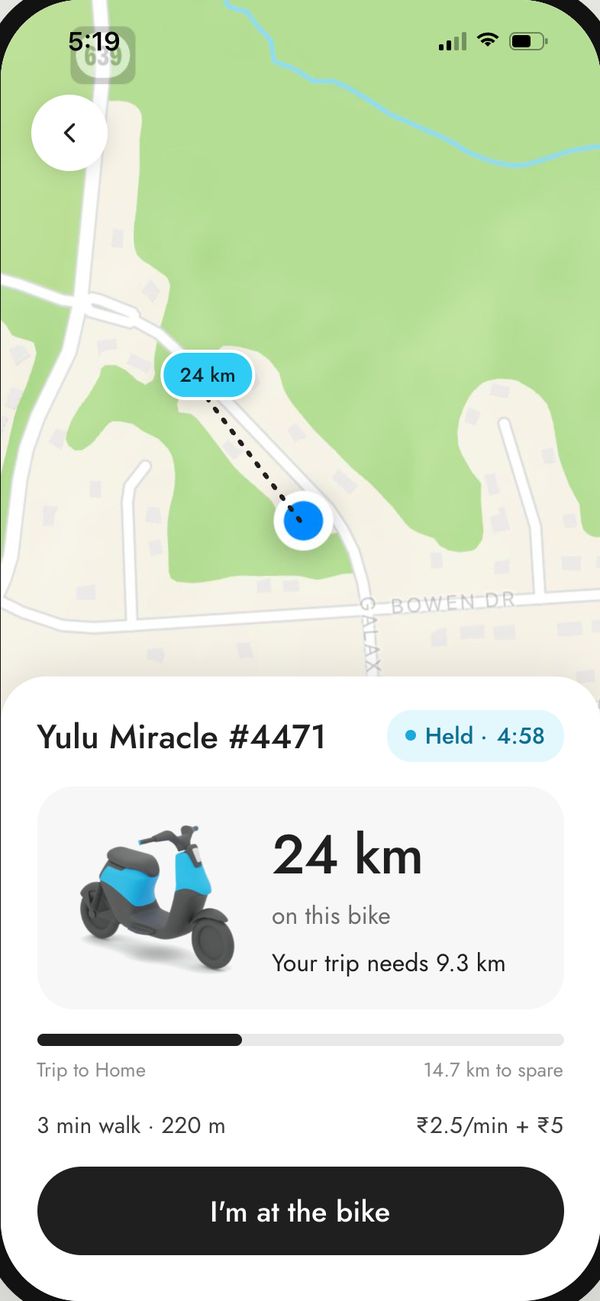
PainShe couldn’t tell what state the bike was in.
Range on this bike against what the trip needs, the margin to spare, and a five-minute hold.
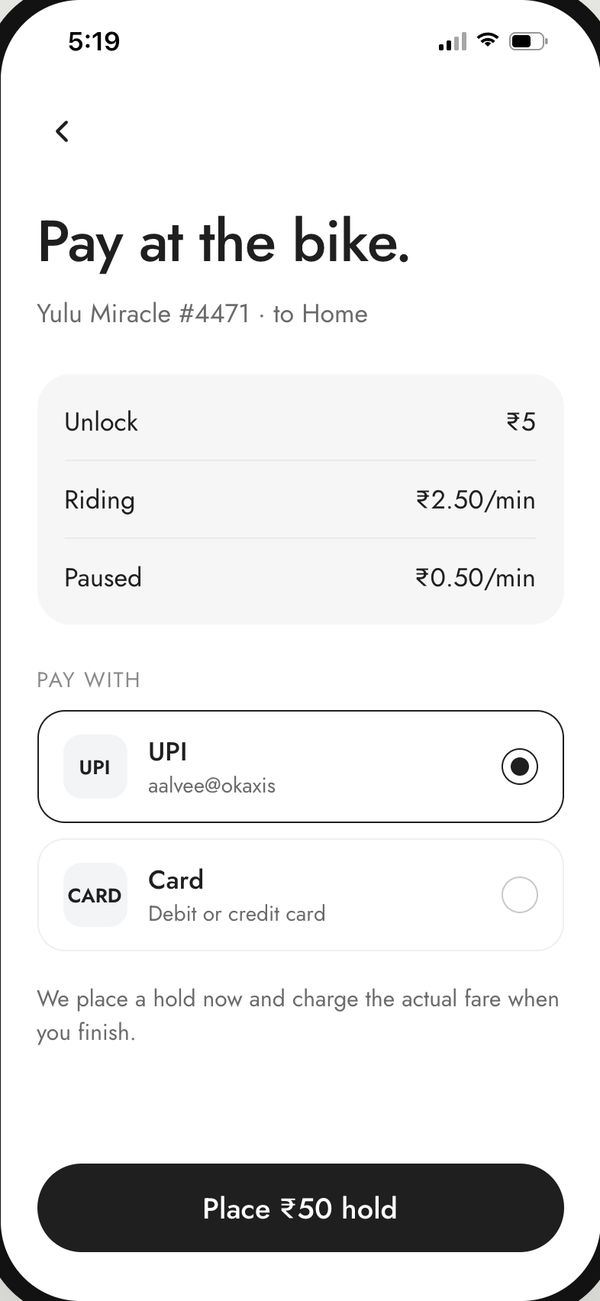
PainA ₹250 deposit and a cash step before riding.
No deposit. A ₹50 hold, and the real fare charged when she finishes.
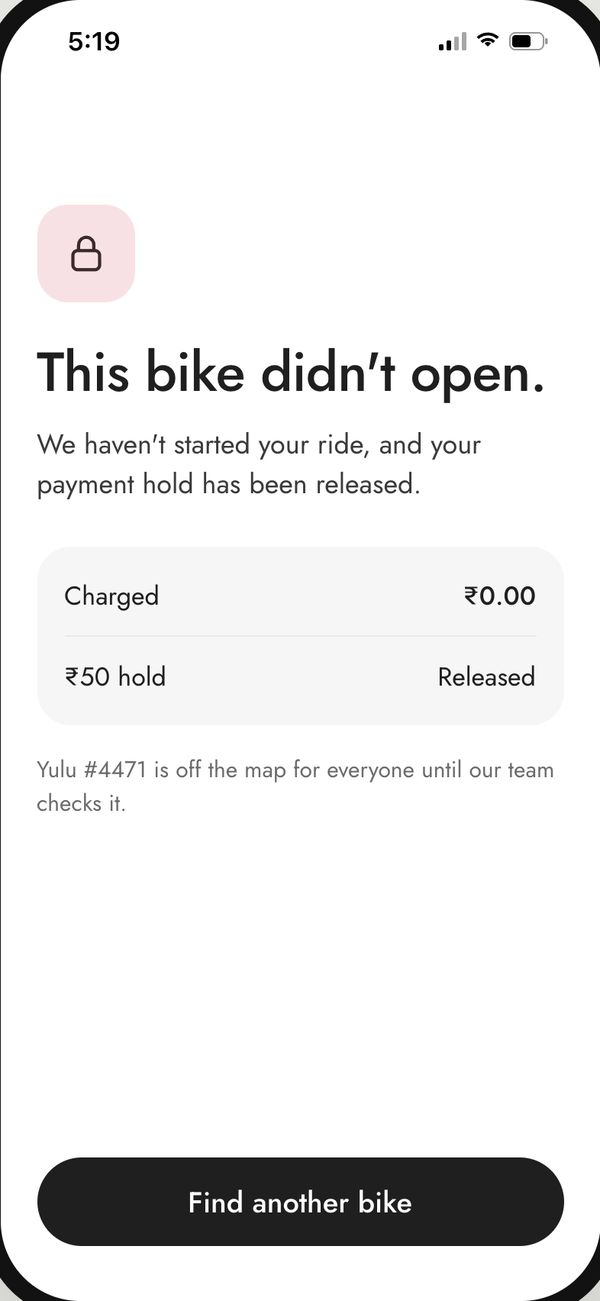
PainA failed unlock that still costs money.
The ride never starts, she’s charged ₹0, the hold is released and the bike leaves the map.
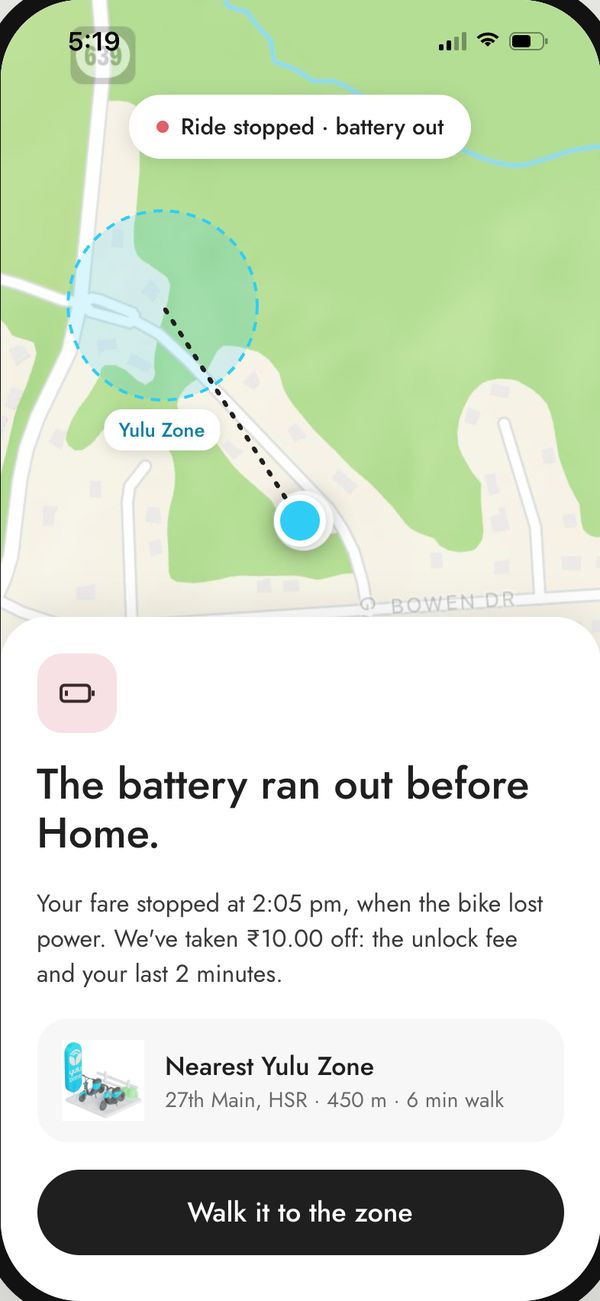
PainThe bike died mid-trip, and she paid for the walk.
The fare stops the moment power is lost, and the nearest zone is one tap away.
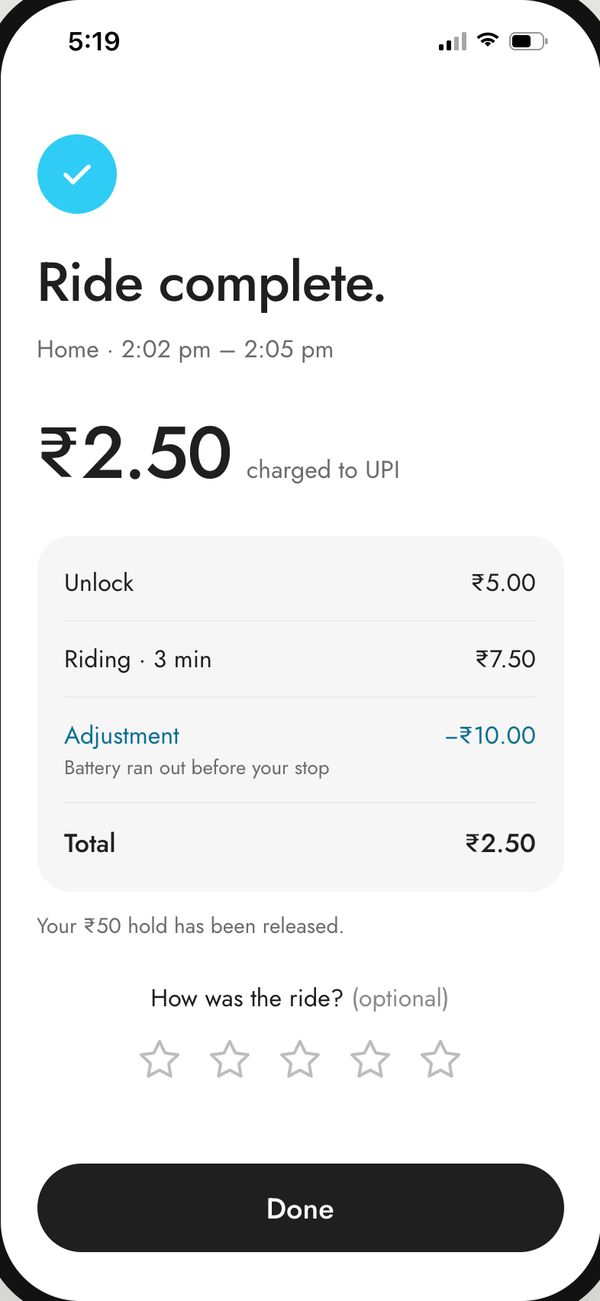
PainWhen the system failed, she carried the cost.
The adjustment is already on the receipt, stated as fact with the reason, and without an apology.
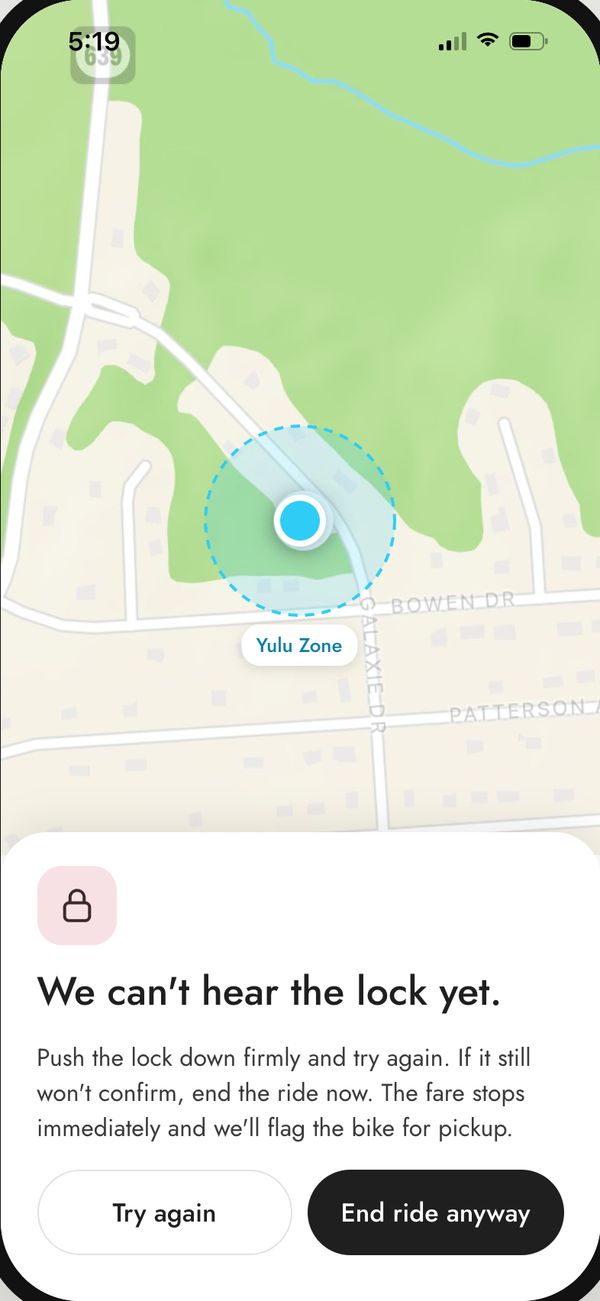
PainA lock that read “locked” but wasn’t.
The app says it can’t confirm. Ending anyway stops the fare and flags the bike for pickup.
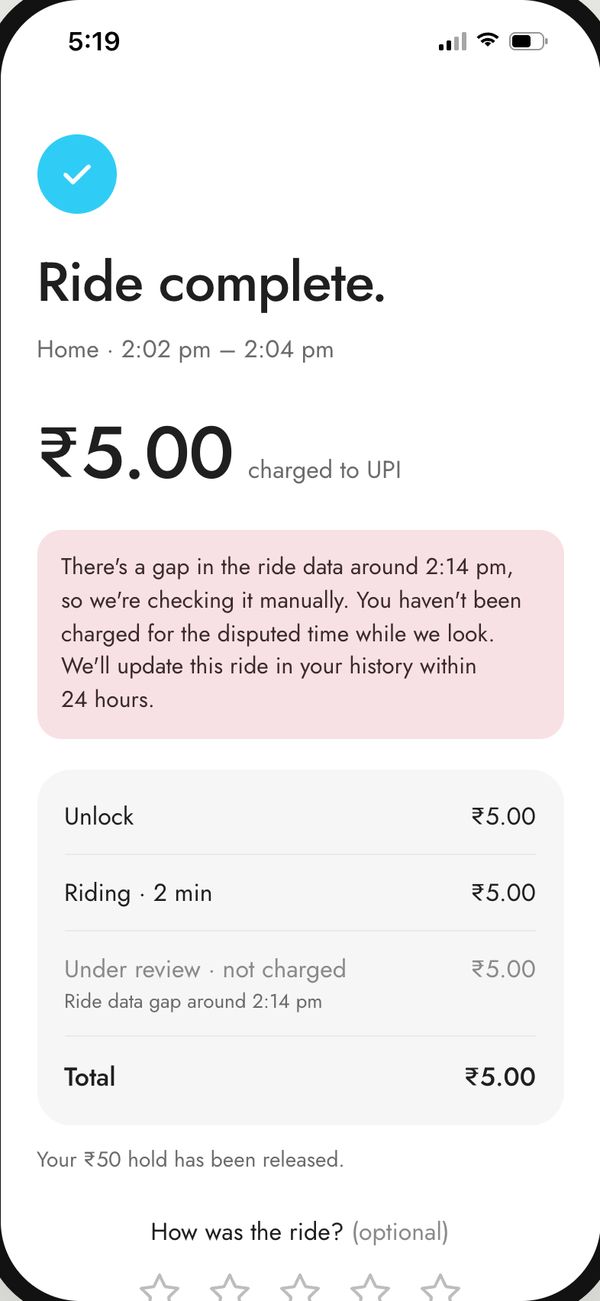
PainA billing dispute nobody could evidence.
The data gap is named, and that part of the ride isn’t charged while it’s checked.
Screens from the working prototype. Try it full screen →
The rubric came before the prompts, so "it reads well" could never be the standard. Scripted scenarios against my own prototype — not user or fleet data.
| Edge case | Source | System response | Rider cost | Verdict |
|---|---|---|---|---|
| Rider's phone dies mid-ride | Model | The bike's lock ends the ride; the fare stops at last confirmed movement. | None | Kept — changed the architecture. The bike, not the app, is the source of truth for ride end. |
| Two riders scan the same bike | Model | First confirmed unlock wins; the second sees the unlock-failure screen, hold released. | Seconds | Kept. Reuses an existing state. |
| Ride ends outside every zone | Mine | End blocked, nearest zone shown, any fee stated before she commits. | A walk | Kept. A fee is never discovered after the fact. |
| Rider spoofs GPS | Model | — | — | Rejected. A different project, and it would pull the product toward suspicion of the user. |
| Fleet-wide outage | Model | — | — | Rejected. Infrastructure, not product behaviour. |
| Rider is under age | Model | — | — | Rejected here. Real compliance work, unrelated to the trust thesis. |
The value isn't in the generation or the filtering — it's in having a written scope sharp enough to filter against.
Three failures stayed in one layer. The fourth lived in the gaps between design, spec and code.
A rider who just wanted to browse had nowhere to go. Fixed with a browsing mode that applies only the 2 km minimum — and says so, never passing a basic check off as a trip check.
The spec forbade it; the prompt never said so. Fixed by making ambiguity escalate explicitly. A value that isn't in the prompt isn't in the product.
Generated code drew every bike, then removed the failing ones — a one-frame flash of bikes that weren't real. Fixed by filtering before drawing.
The marginal-trip notice — the one place an agent speaks up — never fired. The spec gave no number, the code picked 1.2×, and readiness already required 1.5×, so no bike could ever qualify.
The fix touched all three: a thin margin defined as under 1.25× the requirement in the code, the number written into the spec, and the margin shown on the bike preview.
One screen where the AI is invisible, one where it speaks, and one where it admits it was wrong.
Three agents produced this screen; none appear on it. Two hidden bikes are noted in one line, never as a score.
Marginal, not failing. The bike stays bookable, the notice says why it’s tight in words, and her live range stays on screen for the whole ride.
The battery died before her stop. The system stopped the fare at that moment and took the unlock fee and her last two minutes off before she had to ask — stated as fact, with the reason, no apology.
Being able to say why a capability isn't AI is what separates a product from a demo.
The asymmetry rule sat in my spec with zero effect until it was written into the prompt.
Wireframe, spec and code were each correct — and the product still had a hole in it.
The most valuable model output was "you would not draw retention conclusions from this data" — it cost me the claim I most wanted to make.
Trust is built or destroyed in five of seventeen screens.
If the rider never sees the intelligence, someone else has to.